Semantic similarity helps find related text; graphs help traverse explicit relationships and paths.
Working thesis: Vector search and graph retrieval answer different questions and are often complementary.
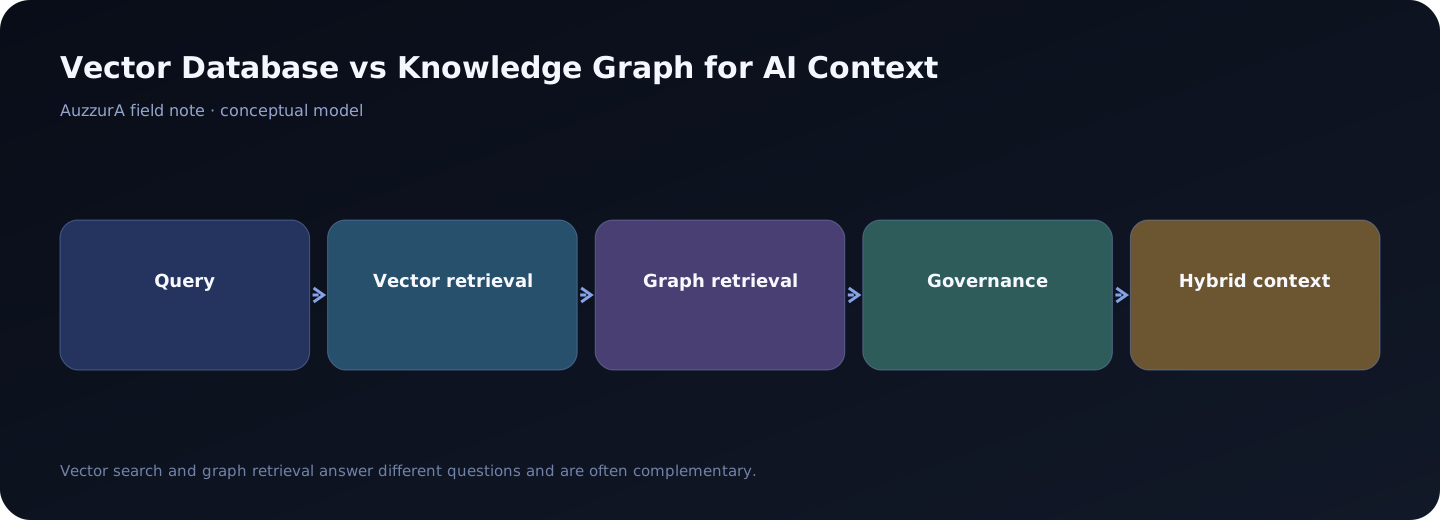
Vector database vs knowledge graph
| Question | Vector database | Knowledge graph |
|---|---|---|
| Best at | Finding semantically similar passages | Traversing explicit entities, edges and paths |
| Useful query | “Find guidance like this incident” | “Which services depend on this component?” |
| Main dependency | Good embeddings and chunking | Reliable entities, relationships and updates |
| Common risk | Similar text can be out of scope or stale | A graph edge can be structurally true without being an approved rule |
| Strongest pattern | Fast candidate retrieval | Relationship-aware expansion and explanation |
Neither structure is the authority layer. Both can help a context composer find evidence, while lifecycle, scope, permissions and human review determine what may be reused.
Why this matters for AI agents
An AI agent does not work from organizational reality directly. It works from the instructions, tools, memory, retrieved material and task state that reach its context window. That makes context selection part of the system architecture rather than a cosmetic prompt decision.
For one-off assistance, an imperfect context set may produce an inconvenient answer. For long-running or tool-using agents, the same weakness can persist across steps, be written into memory, propagate to another agent, or influence an external action. The engineering target is therefore not maximum information. It is sufficient, current and applicable information for the task at hand.
This is also why raw retrieval metrics tell only part of the story. A system can retrieve text that is semantically relevant yet still be wrong for the current project, user, environment or point in time. Conversely, an important constraint may have low lexical similarity to the user’s request but still be essential to safe execution.
A concrete example
Use vectors for guidance similar to an incident, graphs for services affected through dependencies, and a hybrid for applicable guidance with explanation.
A practical architecture
- Query. Keep the stage contract explicit so inputs, outputs and metadata remain inspectable.
- Vector retrieval. Keep the stage contract explicit so inputs, outputs and metadata remain inspectable.
- Graph retrieval. Keep the stage contract explicit so inputs, outputs and metadata remain inspectable.
- Governance. Apply ownership, scope, lifecycle and approval before this state can be reused.
- Hybrid context. Compose the smallest useful task-specific set and retain why each item was selected.
Design principles
-
Choose retrieval structures based on query shape.
-
Keep canonical IDs across indexes.
-
Do not duplicate authority logic inside every retrieval store.
-
Keep provenance, lifecycle state and permissions attached as context moves across tools and handoffs.
-
Evaluate context quality against the task outcome, not only similarity scores or token counts.
How AuzzurA approaches this
AuzzurA focuses on the transition from evidence to usable organizational context. That means keeping provenance, ownership, scope and lifecycle visible instead of treating a document store or retrieval index as the final answer.
Questions to ask before implementing this pattern
- What exactly are we persisting: raw source, memory, candidate knowledge or approved knowledge?
- Who owns an item, and who can change its status?
- How is scope represented across organization, team, project, environment, user, agent and task?
- How do we know when an item is stale, superseded or in conflict?
- Can we reconstruct which context reached a participant during a specific run?
- What learning from the run should return to shared context, and what review is required before reuse?
These questions tend to outlast individual model, vector-store and graph-engine choices because they define the organizational semantics around those components.
Sources and further reading
- Microsoft Research — GraphRAG
- A Survey of Context Engineering for Large Language Models
- Google Cloud Knowledge Catalog — data context
One team. One workflow. One governed loop.
Test AuzzurA with a single agent workflow in 2–4 weeks.