Agents retrieve from organizational sources that contain stale, conflicting and differently-authoritative information.
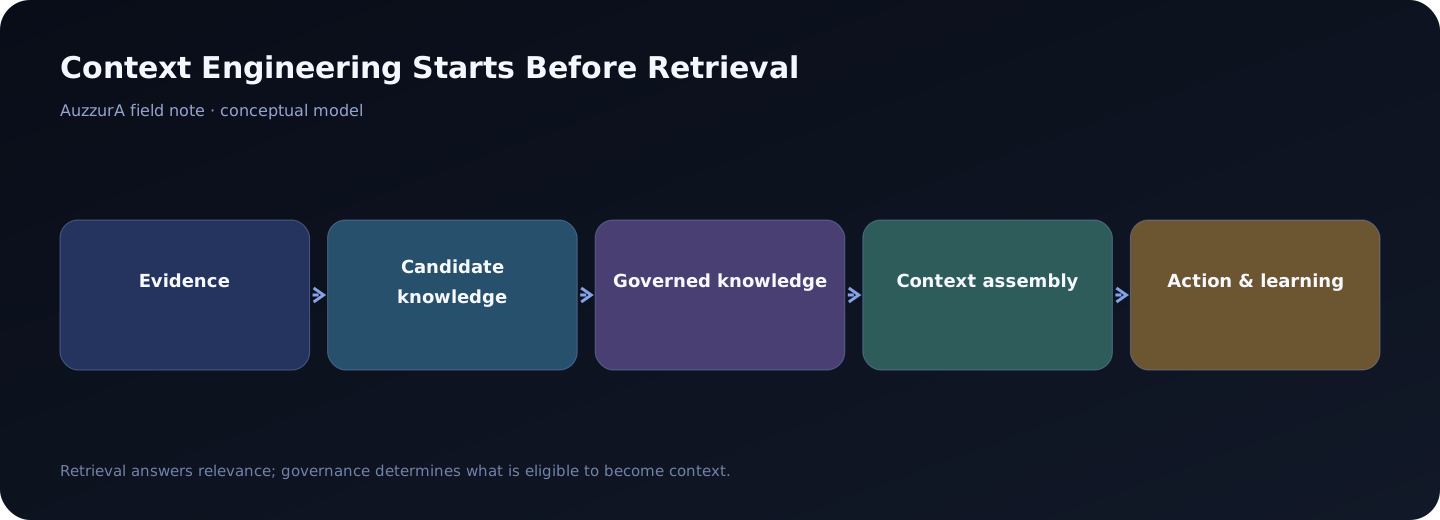
Working thesis: Retrieval answers relevance; governance determines what is eligible to become context.
Why this matters for AI agents
An AI agent does not work from organizational reality directly. It works from the instructions, tools, memory, retrieved material and task state that reach its context window. That makes context selection part of the system architecture rather than a cosmetic prompt decision.
For one-off assistance, an imperfect context set may produce an inconvenient answer. For long-running or tool-using agents, the same weakness can persist across steps, be written into memory, propagate to another agent, or influence an external action. The engineering target is therefore not maximum information. It is sufficient, current and applicable information for the task at hand.
This is also why raw retrieval metrics tell only part of the story. A system can retrieve text that is semantically relevant yet still be wrong for the current project, user, environment or point in time. Conversely, an important constraint may have low lexical similarity to the user’s request but still be essential to safe execution.
A concrete example
A procurement agent can retrieve the semantically closest vendor policy and still get the wrong rule because it is superseded or scoped to another business unit.
A practical architecture
- Evidence. Collect source material with provenance; source access does not make it trusted.
- Candidate knowledge. Turn evidence into a reviewable candidate without silently increasing its authority.
- Governed knowledge. Apply ownership, scope, lifecycle and approval before this state can be reused.
- Context assembly. Compose the smallest useful task-specific set and retain why each item was selected.
- Action & learning. Capture outcomes and route reusable learning back through the appropriate review path.
Design principles
-
Treat source material as evidence, not automatic truth.
-
Apply scope, permissions and lifecycle before context composition.
-
Keep provenance available after summarization.
-
Keep provenance, lifecycle state and permissions attached as context moves across tools and handoffs.
-
Evaluate context quality against the task outcome, not only similarity scores or token counts.
How AuzzurA approaches this
AuzzurA approaches context engineering as a human + AI workflow problem: keep task state, organizational knowledge and source evidence distinct, then assemble only what the current work needs. This is product direction and editorial framing, not a claim that every part of the pattern is shipped.
Questions to ask before implementing this pattern
- What exactly are we persisting: raw source, memory, candidate knowledge or approved knowledge?
- Who owns an item, and who can change its status?
- How is scope represented across organization, team, project, environment, user, agent and task?
- How do we know when an item is stale, superseded or in conflict?
- Can we reconstruct which context reached a participant during a specific run?
- What learning from the run should return to shared context, and what review is required before reuse?
These questions tend to outlast individual model, vector-store and graph-engine choices because they define the organizational semantics around those components.
Sources and further reading
- Anthropic — Effective context engineering for AI agents
- A Survey of Context Engineering for Large Language Models
- ContextNest: Verifiable Context Governance
- Governed Shared Memory for Multi-Agent LLM Systems
- AIM: A Privacy-Aware Interoperable Memory Framework for Multi-Agent Multi-User LLM Systems
One team. One workflow. One governed loop.
Test AuzzurA with a single agent workflow in 2–4 weeks.